Why a Cat Classifier Needs So Many Examples
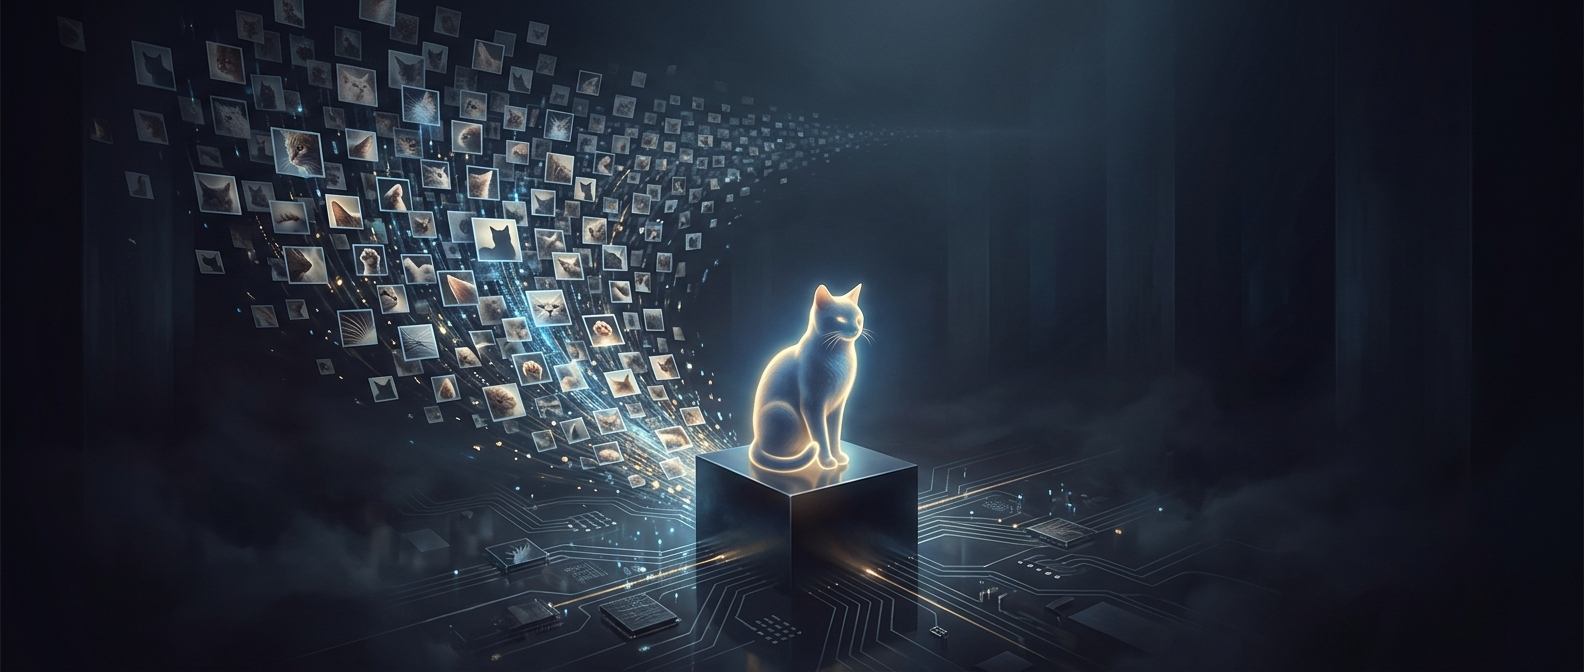
A computer does not begin with a human’s idea of a cat. It begins with numbers representing pixels: patterns of light and color. In a labeled training set, each image is paired with an answer, such as “cat” or “not cat.” The system adjusts its internal calculations to make its guesses agree with those answers, then repeats the process across many examples.
One picture can teach a misleading lesson. A cat photographed on a couch may share more visible features with the couch than with a cat photographed outdoors. Thousands or millions of varied, correctly labeled images help the system separate useful clues—such as shapes, edges, and arrangements of features—from incidental ones like background, lighting, or camera angle.
Why Burnt Toast Can Fool It
Recognition is not the same as understanding. A model may learn that certain dark, irregular patterns often appear in cat images without grasping what a cat is. Burnt toast can produce a similarly irregular pattern, and a system that relies too heavily on that superficial resemblance may classify it incorrectly.
More examples give the model opportunities to encounter cats in different poses, settings, and lighting, as well as things that resemble them. They do not guarantee perfect recognition: the labels must be useful, and the images must represent the situations the system will face. The practical lesson is that a classifier learns from the range of examples it sees—not from a definition of “cat” written in its own mind.