What “inverting” a binary tree actually does
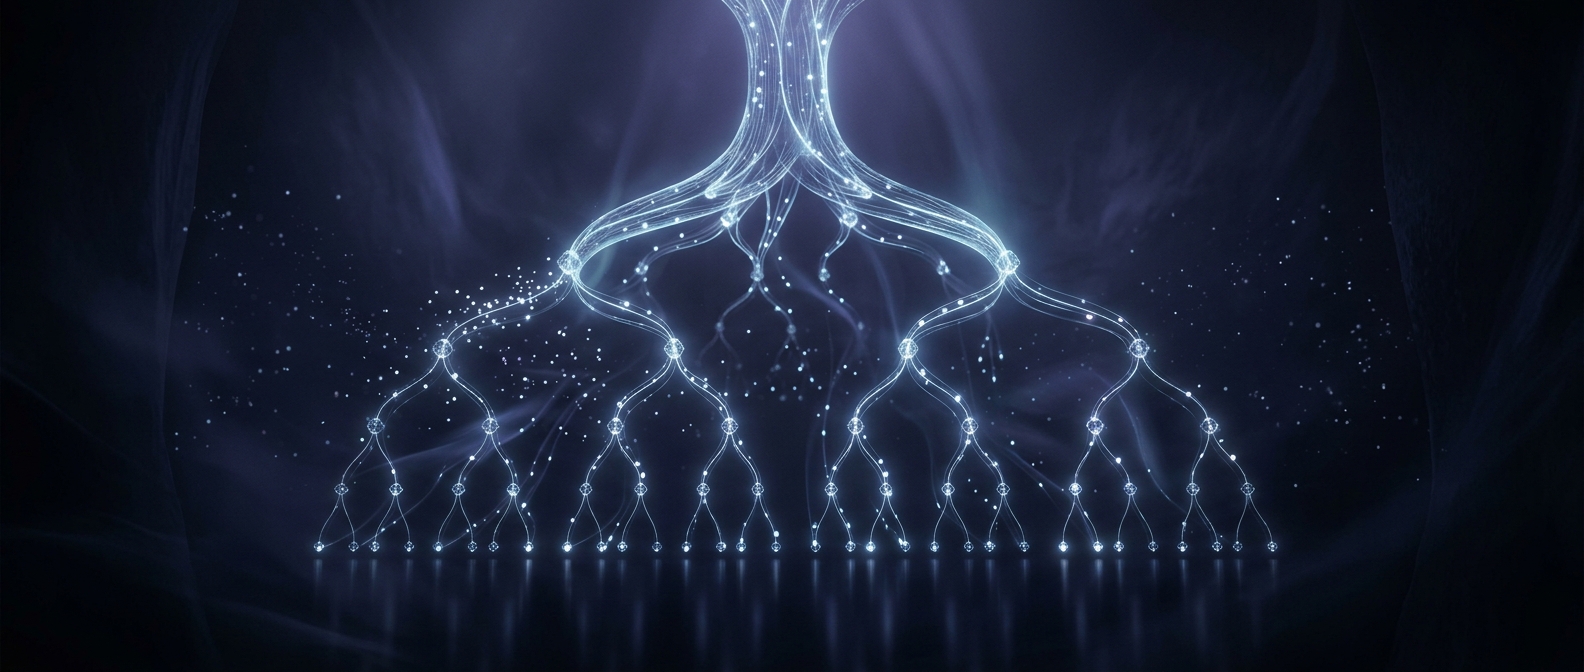
A binary tree stores each item in a node, which can point to a left child and a right child. To invert the tree, a program swaps those two child pointers at every node. The result is a mirror image: branches that went left now go right, and vice versa.
That operation does not, by itself, sort the stored values. In a binary search tree, smaller values are conventionally placed on the left and larger ones on the right. Mirroring such a tree generally reverses that arrangement. Sorting is a different operation: for example, reading a binary search tree in the correct left-to-right order produces its values in sorted order.
Why it makes a useful interview problem
The code can be short, but the task checks whether someone understands how a tree is connected. A recursive solution visits a node, swaps its children, then repeats the process on each child. Recursion means a function handles a smaller version of the same problem by calling itself. An iterative solution can do the same work with a queue or stack.
Either way, every node must be visited, so the work grows in proportion to the number of nodes. The recursive version also uses space for its chain of function calls; that chain is deepest when the tree is especially tall and narrow.
A simple change with a visible result
Inverting a tree is useful when a program needs the structure mirrored—for instance, to change how a tree-shaped interface is laid out or to transform a representation for a particular task. But it is not a routine way to reorder data for sorting. Its value as an interview exercise is that a small, concrete operation exposes common challenges: remembering to process every node, handling an empty branch, and understanding that changing links changes the structure’s meaning.
The memorable distinction is simple: inversion rearranges branches; sorting arranges values. A mirrored tree may look orderly, but its values are not necessarily in sorted order.