What an A/B test can—and cannot—tell a design team
A button that gets more clicks is not automatically a better button. It might attract attention while leading to fewer completed purchases, more accidental taps, or a confusing next step. Before a test begins, the team has to decide which user action counts as success and how it will be measured.
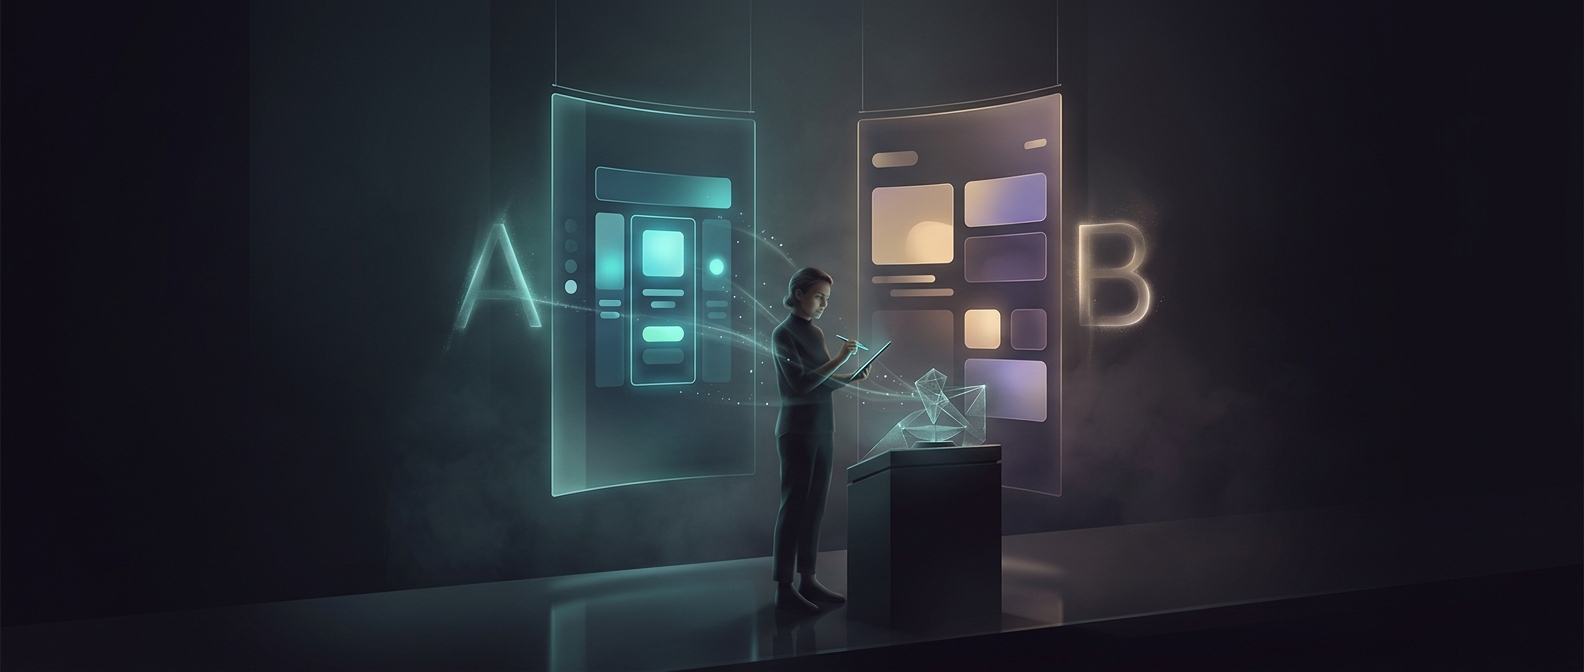
That choice turns a vague design question into a comparison. One version might put a button near a headline; the other might place it lower on the page. The test then tracks the chosen outcome—such as completed sign-ups—rather than relying only on what looks appealing to the designers.
Why the numbers need time
Users behave differently by chance, even when they see the same design. A small early lead can reflect an unusual handful of visitors, not a genuine advantage. As more people encounter each version, random ups and downs tend to matter less, and the comparison becomes more informative.
Teams also need to account for the fact that they may be measuring several outcomes or running many tests. If they keep checking results and stop the moment one version appears ahead, they can mistake a temporary fluctuation for a reliable improvement. A sound test therefore needs a clear success measure and a planned way to judge the evidence.
A local win can have a wider cost
The result applies most directly to the people and conditions included in that test. A button that works better for one audience, device, or moment may not do so for another. And optimizing one measure can harm another: more clicks may mean less clarity, for example.
The practical value is not that experimentation replaces design judgment. It gives teams a way to check whether a specific change actually helps users do what they came to do. A placement tweak that looks minor on screen can be kept, revised, or discarded based on what happens after the click—not just the click itself.