Autoplay starts with a pool of possible tracks
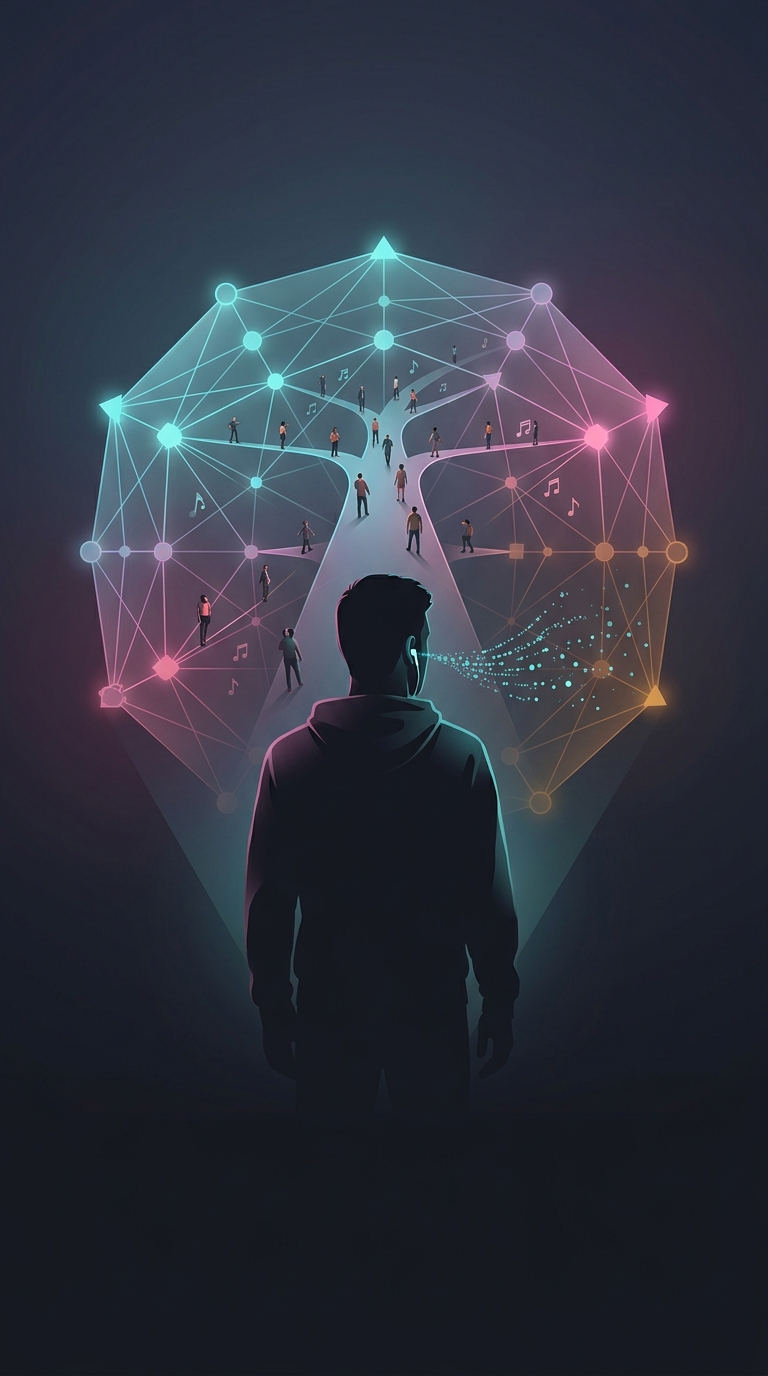
When a playlist runs out, a streaming service usually has to choose from far more music than it can play next. It first narrows the field to plausible candidates: songs connected to the playlist, artists or tracks the listener has played, and music that listeners with similar habits tend to enjoy. The exact mix varies by service, and some tracks may be unavailable because of regional rights or account settings.
The ranking is a prediction, not a simple popularity contest
The service then estimates which candidate is a good fit for this listener at this moment. It can weigh signals such as listening history, recent skips, saves, repeats, and how the current playlist sounds. A track that fits the playlist’s style may rank well even if it is not a global hit; a familiar favorite may be a safer choice than something new.
These signals are clues, not a direct statement of taste. A skip might mean “not now,” rather than “never,” so systems typically rely on patterns across many interactions instead of treating one action as a verdict. The aim is to balance familiarity with discovery while reducing the chance that the next song feels jarring.
Each play helps shape the next choice
After a song plays, the listener’s response becomes another signal. Finishing it, skipping quickly, or saving it can all help refine later recommendations. This creates a feedback loop: the algorithm makes a prediction, observes what happens, and adjusts what it considers a promising match.
That is why autoplay can feel uncannily well suited—or suddenly miss the mark. It is not selecting the one objectively correct next song; it is ranking guesses from incomplete evidence, then learning from what the listener does.