How OCR Turns a Page into Searchable Text
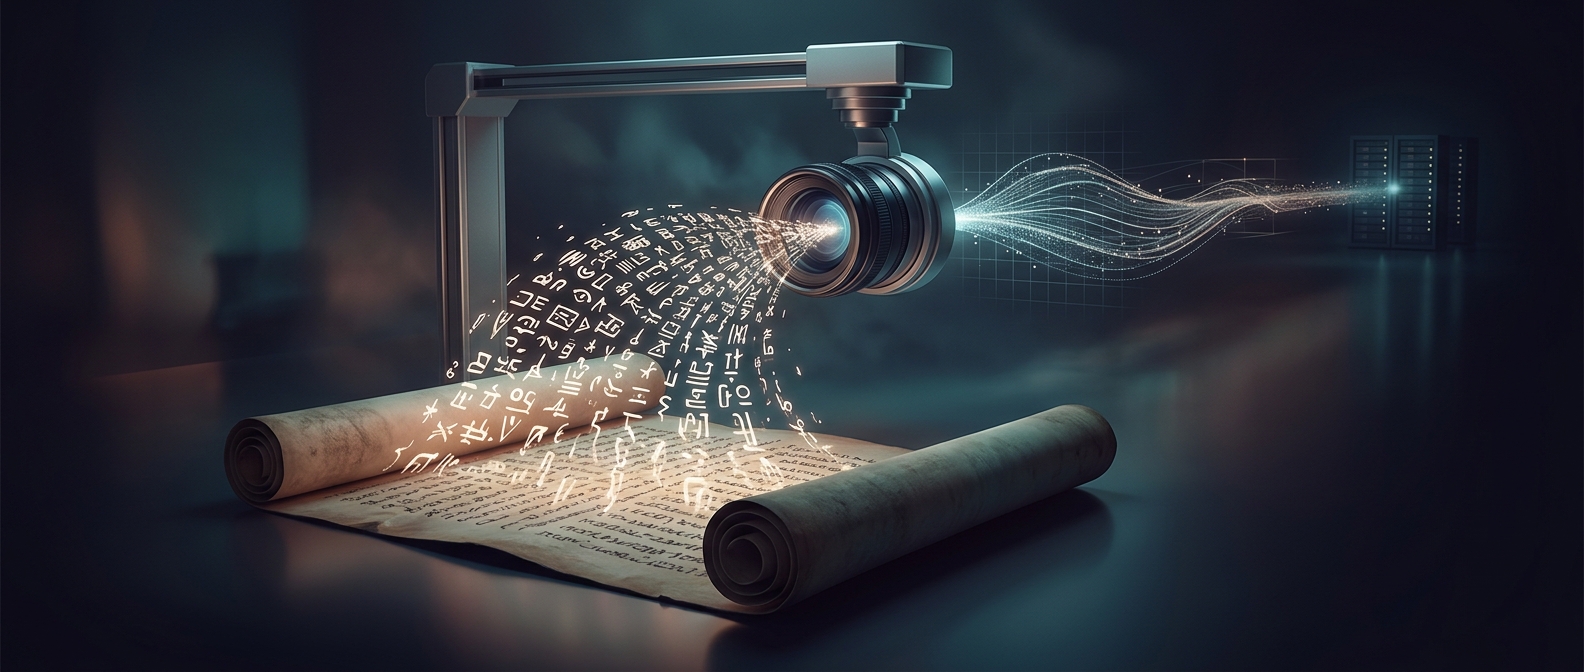
Before software can recognize words, it has to locate them. An OCR system analyzes an image for likely lines and regions of text, then separates those regions into smaller shapes. Skewed pages, uneven lighting, ornate fonts, and tightly packed columns can all complicate that first step: if the system groups two letters together—or splits one letter apart—the later guess starts from a distorted clue.
Recognition Is a Sequence of Decisions
Older approaches often compared individual character shapes with stored patterns. Many modern systems instead analyze stretches of text, using neural networks trained on examples of printed or handwritten writing. They learn which visual features tend to correspond to letters, but the image may not provide enough evidence to settle a character on its own.
That is where context helps. If a blurry mark could be an “o” or an “u,” the letters around it may make one resulting word more plausible. This improves the reading of ordinary sentences, but it can also introduce errors: a familiar word may be chosen over an unfamiliar name, a technical term, or an unusual spelling. Context narrows the possibilities; it does not restore missing ink.
Why a Small Error Can Matter
OCR output is useful because text becomes searchable, selectable, and easier to reuse. But recognition mistakes can travel into archives, scanned records, and copied documents without looking obviously wrong. A person searching for a name may miss it because one letter was misread, while a software system processing the text may treat the mistaken version as accurate.
The clearest scans give OCR the best chance, but checking the result matters most where exact wording counts: names, dates, amounts, and other details that a reader cannot safely infer from context.