Why So Much Online Content Never Appears in Search
A search engine does not inspect every page on the internet each time you search. It first discovers pages by following links and other signals, then stores selected information about them in an index—a searchable catalog built ahead of time. If a page is never discovered, cannot be read by the crawler, or is not considered suitable to index, it may not appear in ordinary search results.
Some barriers are deliberate. Banking sites and company intranets require sign-in, so their contents are meant for authorized users, not public crawlers. Other material sits behind a search box: a library database may generate a page only after someone chooses a journal, date, or keyword. Because that page may have no permanent public link, a crawler cannot reliably find it by following links.
“Unindexed” Does Not Mean Hidden in One Place
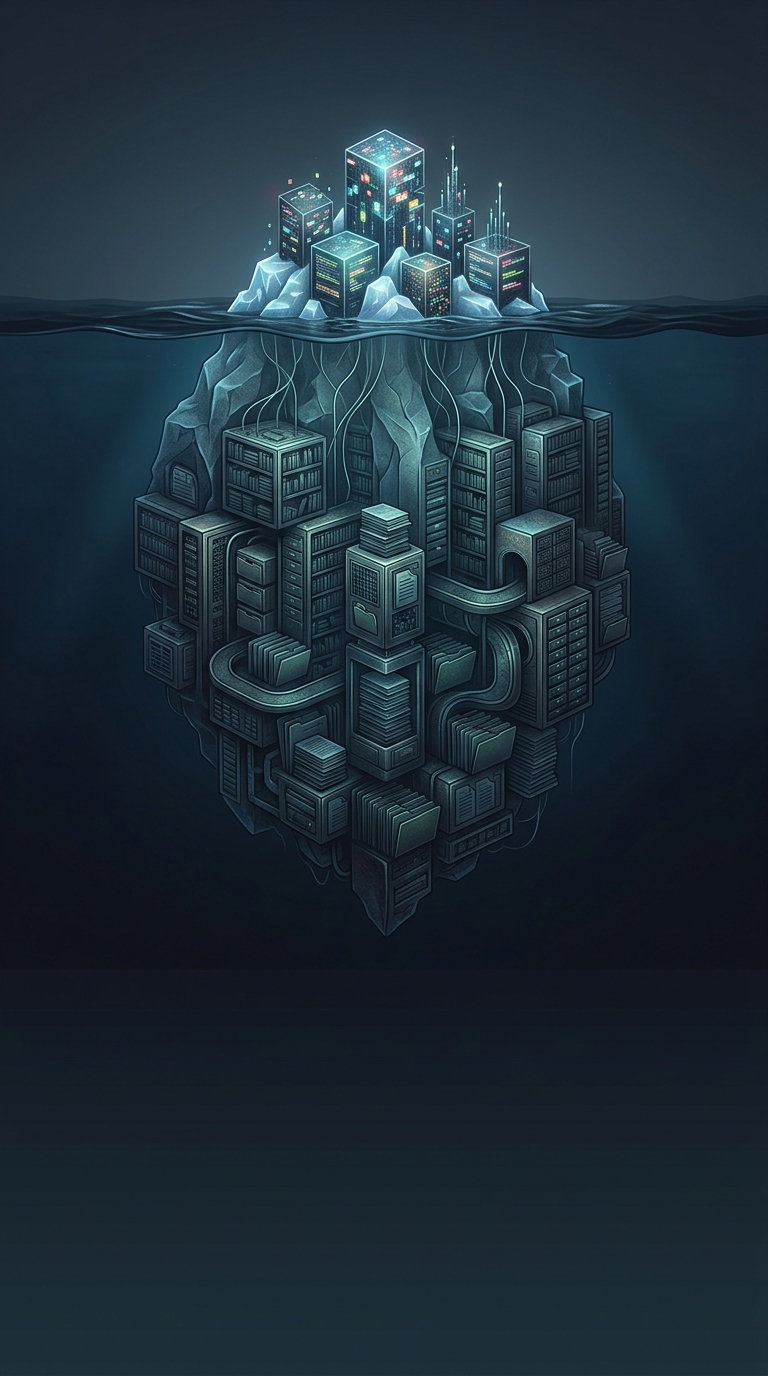
The deep web is a broad label for online content that standard search engines do not index. It is not a separate network or a single repository. It includes private pages, database results, and other material that ordinary search cannot retrieve. The “dark web,” by contrast, refers to services that require specialized software or configurations to access; the terms are not interchangeable.
Even public pages can be left out of an index if a site blocks crawlers, the page is temporary or duplicative, or the engine has not yet discovered it. So the boundary is practical, not mysterious: search engines can find and catalog only what they can access and interpret. A web search may locate a university’s public catalog, for instance, while the articles and account tools available after login remain beyond its reach.