A Warehouse Robot Builds a Map With Meaning
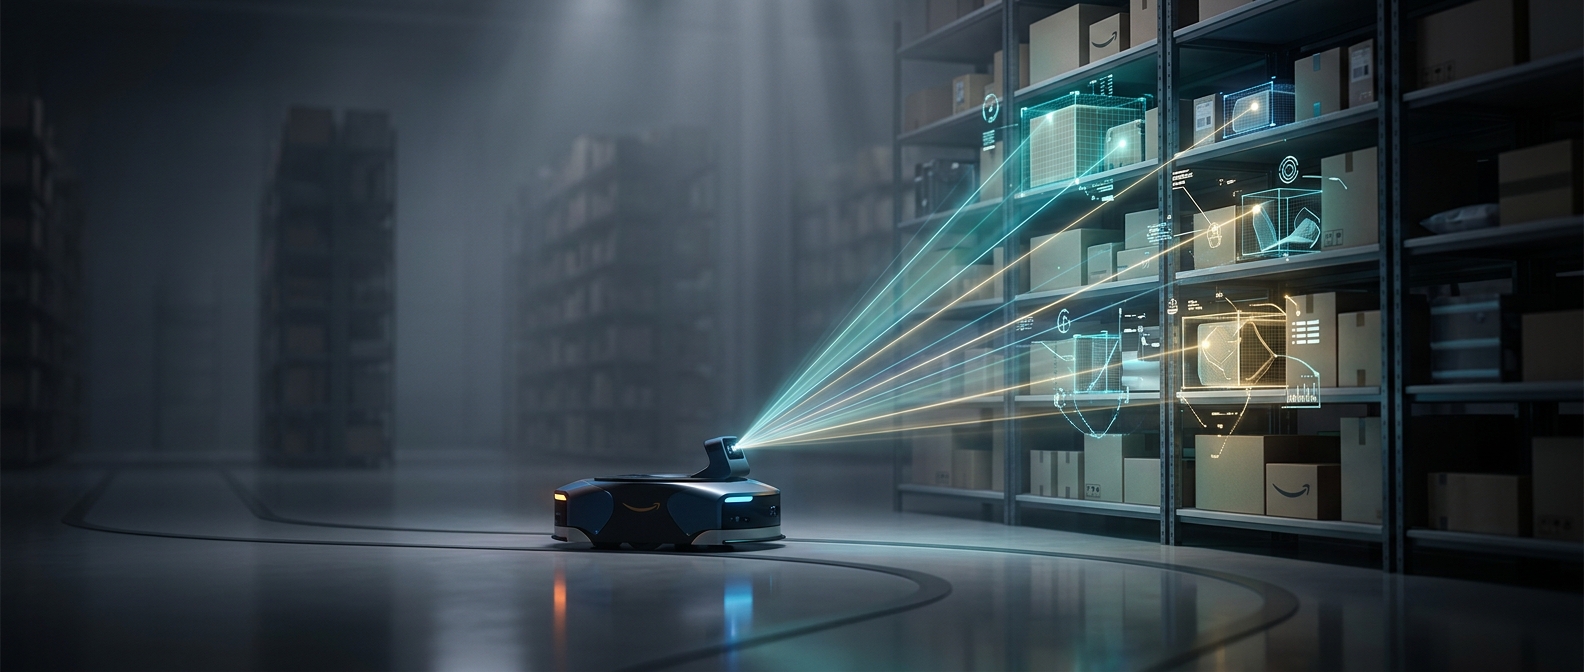
A conventional map can tell a robot that a patch of space is occupied. A semantic map adds a useful distinction: it records what the robot thinks is there. Cameras can supply visual cues such as color and shape; depth sensors or lidar— which measures distance with laser pulses—help locate those cues in three-dimensional space. Software combines the observations and assigns likely labels, such as person, pallet, box, or pillar.
The result is not just a picture of obstacles. It is a working map in which objects can call for different responses. A pillar is a fixed obstruction to route around. A box may be temporary or movable. A person is likely to move, so the robot must leave room for that movement rather than treating the person as part of the building.
Why the Label Changes the Route
The robot continually compares new sensor readings with its map. If a person appears in a travel lane, the system can track the person’s changing position and adjust its path or pause. If the same area contains a pillar, the robot can plan a stable detour around it. This distinction helps prevent a route planner from making the crude choice to treat every detected shape the same way.
Labels are estimates, not perfect knowledge. A worker partly hidden behind a shelf may be difficult to classify, and a box can obscure what is behind it. When the view changes, the robot can update its map from fresh observations. The practical advantage is that navigation can respond not only to where an obstacle is, but also to what kind of obstacle it appears to be.